AI crawlers can consume bandwidth, trigger expensive application requests and collect pages for very different purposes. Before blocking them, decide whether you want to restrict model training, preserve AI search discovery, or reduce request volume. Those goals need different controls.
Use robots.txt to state crawl preferences, Apache or Nginx rules to reject matching requests, and scoped rate limits when limited access is acceptable. A user-agent header can be forged, so none of these examples identifies a real bot by name alone. Start with one site, keep a configuration backup and verify normal visitors still receive the expected pages.
Choose Which Crawlers and Uses to Restrict
Build a small registry from official provider documentation: record each token, purpose, intended policy, verification source and last review date. A long blocklist is not necessarily a correct one. The following distinctions were checked on 23 September 2026; review them again when a provider changes its documentation or your logs show a new agent.
| Agent or token | Documented purpose | Policy consideration |
|---|---|---|
| GPTBot | OpenAI model-training crawler. | Its crawl preference is separate from ChatGPT search discovery. |
| OAI-SearchBot | Discovery for ChatGPT search. | Allow separately if that visibility matters. |
| ClaudeBot / Claude-SearchBot | Model development / search optimization, respectively. | Choose a policy for each purpose. |
| PerplexityBot | Surfaces and links websites in Perplexity search; not foundation-model training. | Blocking it can restrict discovery. |
| ChatGPT-User / Perplexity-User / Claude-User | User-requested retrieval. | Check each provider’s rules; do not assume training-crawler controls cover these requests. |
| Google-Extended | A robots.txt product token controlling specified Gemini training and grounding uses. | It has no separate HTTP user-agent and does not control Google Search inclusion or ranking. |
Sources: OpenAI’s crawler reference, Anthropic’s bot guidance, Perplexity’s crawler reference, and Google’s Google-Extended definition.
OpenAI says robots.txt rules may not apply to user-initiated ChatGPT-User requests; Perplexity says its user fetcher generally ignores them. Anthropic states that its bots honor robots.txt. Keep these distinctions in the registry instead of treating every name containing “AI” as the same service.
The examples below restrict GPTBot and ClaudeBot as a deliberate policy choice. They leave the separate search agents out of the server blocklist. Add other agents only after checking their purpose and your own goals. Protect private information with authentication and authorization regardless of crawler policy.
Set Crawl Preferences in robots.txt
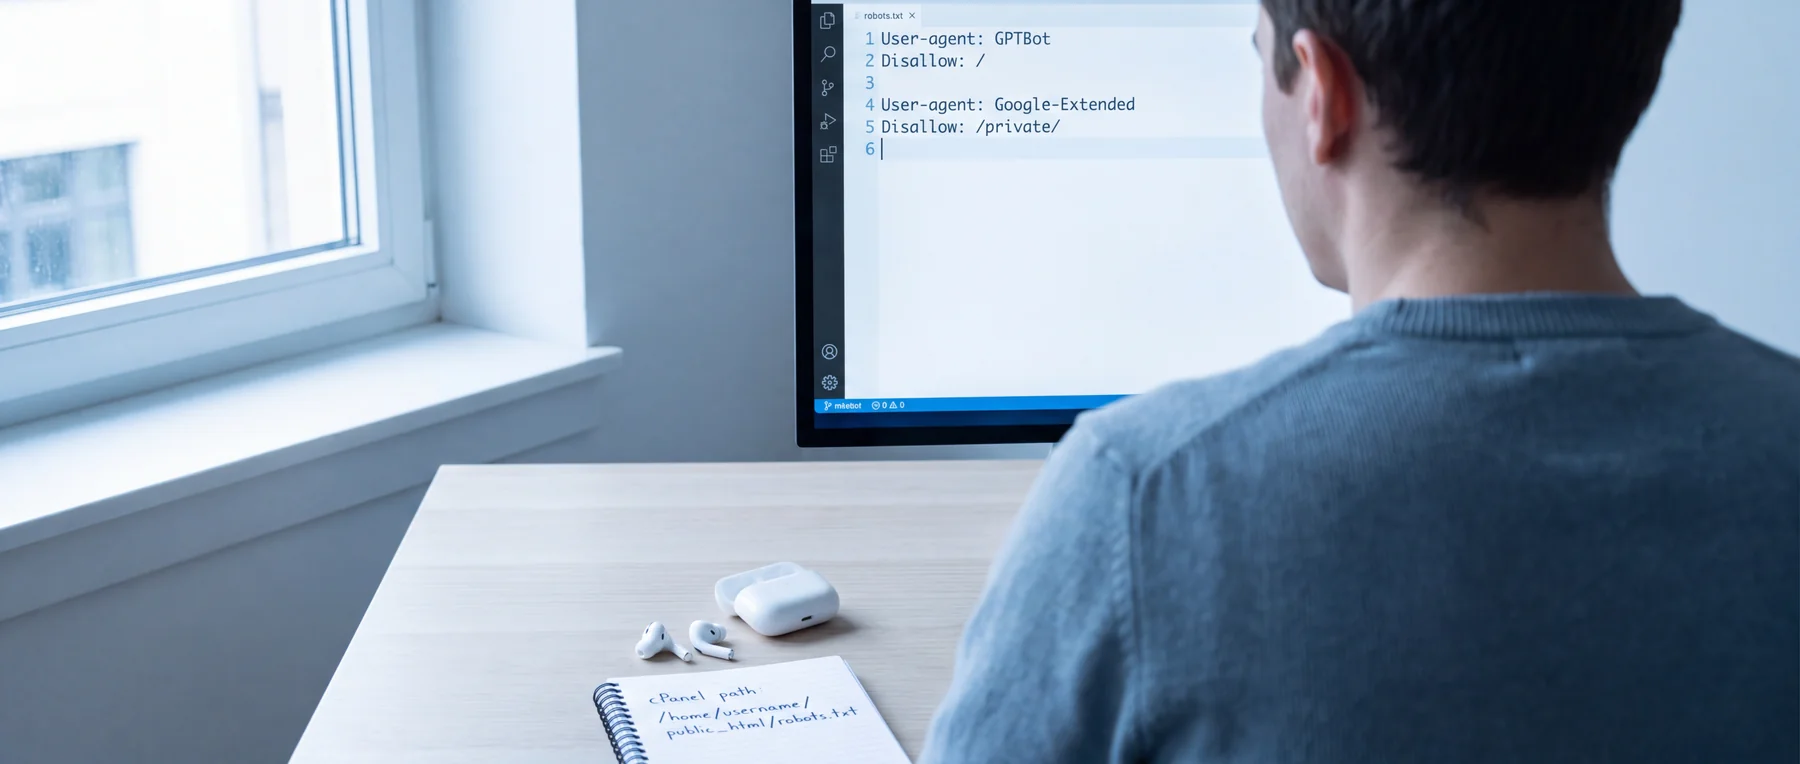
Serve the file at the root of the relevant hostname, such as https://example.com/robots.txt. In cPanel, check the domain’s actual document root before using File Manager; addon domains may not use the main public_html directory. Existing WordPress or SEO-plugin rules must be reviewed before you add another group.
This example requests no GPTBot or ClaudeBot crawling and opts out of the uses controlled by Google-Extended. Merge it with your existing file; retain useful sitemap and site-specific rules.
User-agent: GPTBot
Disallow: /

User-agent: ClaudeBot
Disallow: /

User-agent: Google-Extended
Disallow: /
As specified in RFC 9309, robots.txt is a crawler protocol, not an access-control mechanism. A path listed there remains accessible unless another control restricts it. A more specific bot group also needs all restrictions you intend for that bot; do not assume a wildcard group automatically supplies them.
Check the actual GET response, including headers and body. Replace example.com with your hostname. This command makes no server change:
curl --connect-timeout 10 --max-time 30 --silent --show-error --include https://example.com/robots.txt
Look for a successful response with the intended plain-text rules, not a login screen or an HTML error. If a CDN caches the file, check the public response after the cache updates. Apply your policy to each relevant hostname and protocol endpoint rather than assuming one file governs every subdomain.
Crawl-delay is not a universal throttle. Anthropic documents support for this non-standard extension, but support varies between crawlers. Use a scoped request-rate control when you need enforceable limits. For the distinction between account file access and server administration, see our managed VPS and cPanel guide.
Enforce a Block in Apache or Nginx
Choose the example matching the server that actually handles incoming requests. A CDN, reverse proxy or hosting panel can change where a rule belongs. These snippets are additions to an existing site configuration; preserve its TLS, PHP, proxy and routing settings.
Apache: reject selected user-agent tokens
With mod_rewrite enabled and the necessary FileInfo overrides permitted, place this near the top of the site’s .htaccess file, before application rewrites and outside any plugin-managed block. Confirm module and override support with your administrator first. Back up the file and keep a way to restore it if a request returns 500.
RewriteEngine On
RewriteCond %{REQUEST_URI} !^/robots\.txt$ [NC]
RewriteCond %{HTTP_USER_AGENT} (GPTBot|ClaudeBot) [NC]
RewriteRule ^ - [F,L]
The first condition keeps robots.txt reachable so compliant bots can read your policy. The next matches the chosen header tokens without case sensitivity; the F flag produces a forbidden response. It does not verify who sent the request. See Apache’s mod_rewrite reference and our .htaccess guide before combining it with other rules.
Nginx: map the policy, then return 403
Put these maps in the existing http context, outside any server block. They classify the selected headers and exempt the exact robots.txt path.
map $http_user_agent $selected_ai_crawler {
    default 0;
    ~*(GPTBot|ClaudeBot) 1;
}

map "$selected_ai_crawler:$uri" $block_ai_crawler {
    default 0;
    "1:/robots.txt" 0;
    ~^1: 1;
}
Add only this conditional to each relevant existing HTTP or HTTPS server block:
if ($block_ai_crawler) {
    return 403;
}
Nginx documents map placement and matching and conditional returns. Do not add Google-Extended to a header match: its policy belongs in robots.txt. On a systemd installation using the standard service name, validate the complete configuration and reload only after a successful test:
sudo nginx -t && sudo systemctl reload nginx
Then check the public endpoint. A matching header should receive 403 for ordinary content while robots.txt remains accessible. Any client can omit or change its header, so persistent abusive traffic may need additional behavior-based controls at the edge.
Rate-Limit Crawlers You Intend to Allow
Use throttling as an alternative to blocking the same traffic. A server-level 403 return runs before the rate-limit example can help that request. Decide which policy you want, then remove the corresponding block rule when trialing limited access.
For Nginx, place this map and zone in the http context. Only matching headers produce a nonempty key; other clients are excluded from this particular zone.
map $http_user_agent $ai_crawler_key {
    default "";
    ~*(GPTBot|ClaudeBot) $binary_remote_addr;
}
limit_req_zone $ai_crawler_key zone=ai_crawlers:10m rate=2r/s;
Add these directives to the existing server or intended location without replacing application routing:
limit_req zone=ai_crawlers burst=10 nodelay;
limit_req_status 429;
These are example tuning values, not measured safe limits: an average two requests per second per IP and a burst allowance of ten. With nodelay, admitted bursts are not delayed; excessive requests are rejected with the configured 429 status. Review Nginx’s rate-limit reference, especially inheritance: a location with its own limit_req directives does not inherit the parent set.
Behind a proxy, restore the real client address only from explicitly trusted proxies using the real-IP module. Otherwise many requests may share the proxy’s key, or an untrusted forwarded header may be accepted. Verify logs before enforcing a per-IP policy.
Apache’s mod_ratelimit controls response bandwidth, not requests per second. For request-rate limits, use a supported reverse proxy, WAF or CDN feature with matching conditions and logs. Do not install a generic denial-of-service module and assume it specifically throttles AI bots.
Verify Crawler Identity and Test Your Rules
A request saying Googlebot, Bingbot or GPTBot is only making a claim. For a bot you wish to allow, use its provider’s current published IP ranges or documented verification method. Do not allow an entire Google or Microsoft network solely because the provider owns it.
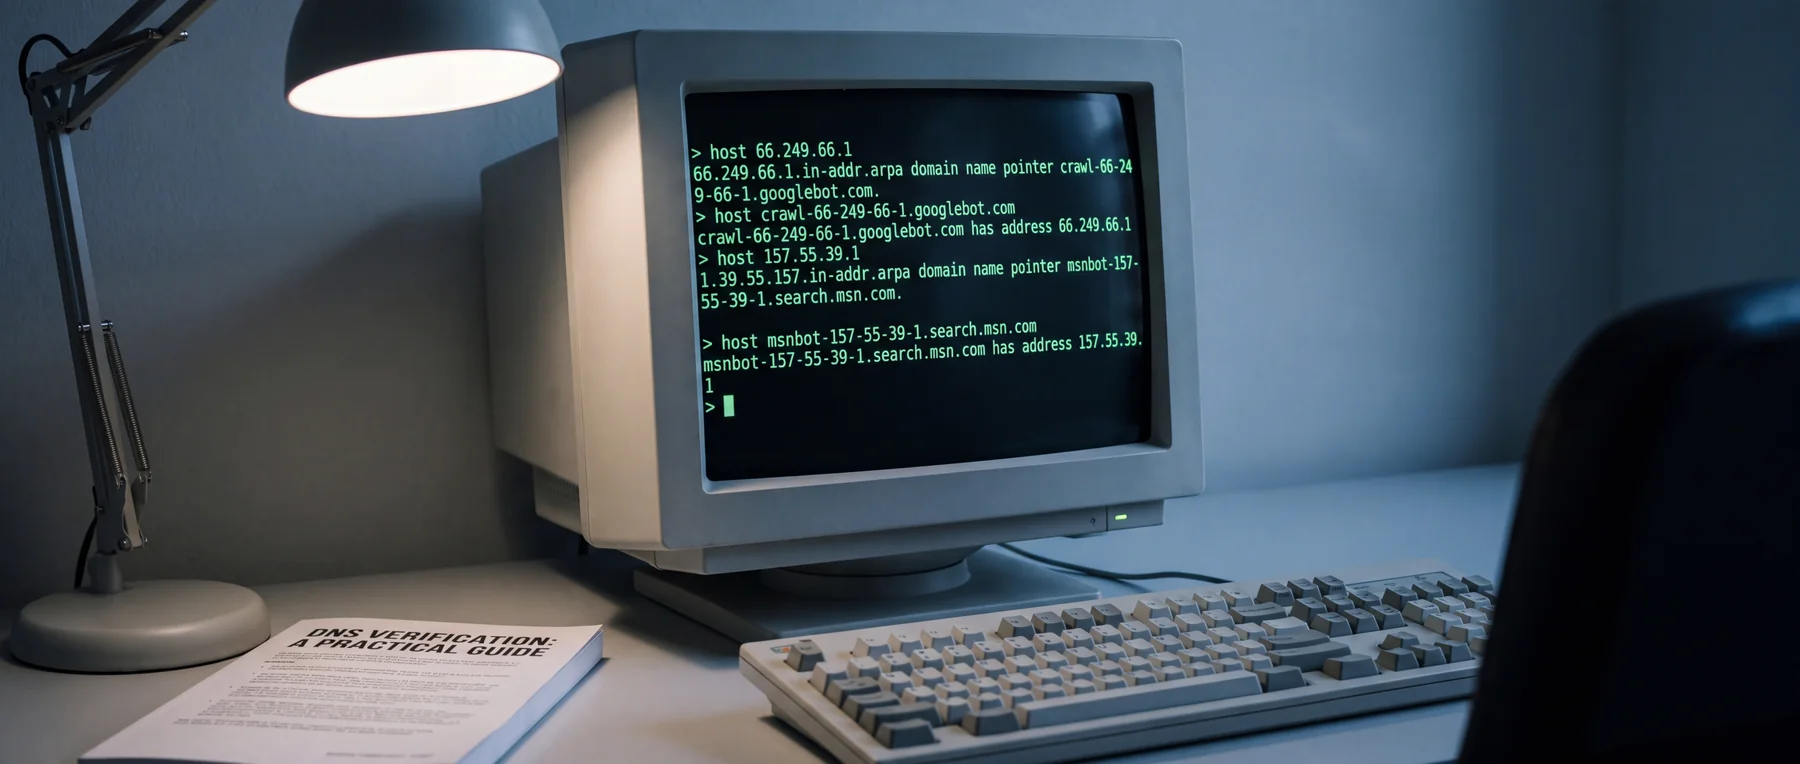
Google’s verification instructions describe reverse DNS followed by a forward lookup. Start with an address from your own logs, verify the returned hostname belongs to the documented crawler domain, and confirm that resolving that hostname returns the original address. Check the domain suffix boundary; a lookalike hostname is not a match. The correct range and hostname depend on the crawler category.
For Bingbot, use Microsoft’s official verification guidance. For other providers, follow the current links in your registry. A successful DNS lookup alone does not establish identity, and the illustrative terminal image is not a live verification result.
Test rule behavior separately from identity. Replace example.com, then run these bounded GET checks on your own site. The printed status verifies your chosen policy; it does not impersonate a verified provider address or prove that a real crawler visited.
for agent in GPTBot ClaudeBot Mozilla/5.0 Googlebot; do
  printf "%s: " "$agent"
  curl --connect-timeout 10 --max-time 30 --silent --show-error \
    --output /dev/null --write-out "%{http_code}\n" \
    --user-agent "$agent" https://example.com/
done
| Check | Expected result | If it differs |
|---|---|---|
| Selected bot header, block policy | 403 for ordinary content; robots.txt stays readable. | Check rule order, the actual serving stack and edge caching. |
| Ordinary browser header | The site’s normal response and working page. | Restore the backup if legitimate traffic is affected. |
| Claimed Googlebot header | No match in this selected-token blocklist. | Inspect broader rules; a successful response is not identity proof. |
| Allowed crawler under rate limiting | Normal traffic passes; excess may receive 429. | Check the key, effective location and logs; a slow sequential test may never reach the threshold. |
Test a few representative paths, including a dynamic page and robots.txt, through the public hostname. Compare edge and origin logs where available. If you exercise a rate limit, use a bounded test on a noncritical endpoint you control; avoid sending bursts to a costly search or checkout path.
Measure the Effect and Keep a Rollback
Record request counts, response bytes, paths, statuses and upstream response times over comparable periods before and after the change. Distinguish traffic served from an edge cache from work reaching the origin. A count of blocked requests alone does not tell you the CPU time or transfer cost saved.
Watch ordinary traffic, search discovery and referral behavior as well as crawler volume. Retain the change only if it meets your stated goal without unwanted exclusions. Record the owner, reason, review date and rollback file for each rule; revisit the registry when providers announce changes.
If you need direct control over Nginx configuration, explore HostStage’s unmanaged Linux VPS options. Choose a stack you can maintain, including backups and updates. If you prefer help administering the server, discuss the required crawler controls before choosing a managed plan.
Frequently Asked Questions
Can robots.txt completely block AI crawlers?
No. It states preferences for compliant crawlers. Use server or edge enforcement when access must be rejected, and authentication for private content.
Can I block training crawlers while allowing AI search?
Yes, where providers expose separate agents. Review the purpose of each token before changing it; training, search and user-requested retrieval are different cases.
Does Google-Extended change my Google Search ranking?
Google says it does not affect Search inclusion or ranking. It controls specified Gemini uses and has no separate HTTP user-agent to block.
Why do requests continue after a user-agent block?
Clients can change headers, rules may cover the wrong endpoint, or traffic may be served elsewhere in the stack. Compare logs and verify the effective rule before expanding it.
Should I block and throttle the same crawler?
Choose one policy for that traffic. In the Nginx examples, a server-level 403 return prevents the request from reaching the rate-limit handling.
Are the sample rate limits suitable for every site?
No. They demonstrate syntax. Select limits from your own workload, test controlled changes and watch for false positives.